This is a blog 5 of a series of blogs about algorithmic challenges I came across when creating tgen.
In this blog we will tackle:
- Generate a skewed connected graph on vertices with edges, in time if is , and in expected time otherwise.
In the previous miniblog we generated a skewed tree with wnext: the parent of is wnext(i, e). If is small, this is biased toward and the tree is star-like; if is large, it is biased toward and the tree is path-like, with endpoints and . To get a connected graph with edges, the obvious next step is to add extra edges uniformly at random. However, if an extra edge connecting the two ends of a long path is chosen, this can collapse the large diameter we are looking for.
Instead, extra edges are ancestor chords of bounded length. After building the same spanning tree as tree::gen_skewed(n, e), an extra edge is a pair where is the -th ancestor of for some (length is already a tree edge). There are such chords, and if is constant, we can list them all and then pick of them uniformly.
std::vector<std::pair<int, int>> gen_skewed(int n, int m, int e, int spread) {
	std::vector<int> parent(n), depth(n, 0);
	std::vector<std::pair<int, int>> edges;
	parent[0] = 0;
	for (int i = 1; i < n; i++) {
		parent[i] = wnext(i, e);
		depth[i] = depth[parent[i]] + 1;
		edges.emplace_back(parent[i], i);
	}

	std::vector<std::pair<int, int>> candidates;
	for (int u = 0; u < n; u++) {
		int v = parent[u];
		int max_k = std::min(spread, depth[u]);
		for (int k = 2; k <= max_k; k++) {
			v = parent[v];
			candidates.emplace_back(v, u);
		}
	}

	for (auto [v, u] : choose(candidates, m - (n - 1)))
		edges.emplace_back(v, u);
	return edges;
}
Algorithm 1: skewed connected graph by listing ancestor chords.
Here, choose returns a uniformly random subset of the given size.
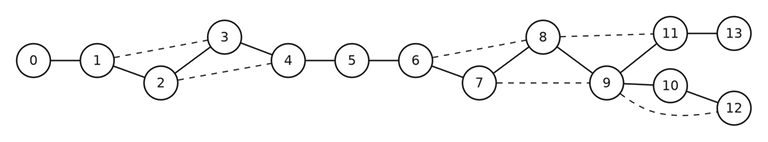
Algorithm 1 with , , , (path-like). Solid edges are the spanning tree; dashed edges are ancestor chords.
The spanning tree is computed in time (each wnext is ). Inserting edges into adjacency sets costs each. If is , Algorithm 1 runs in time.
If is large, that list is too big, up to . Interestingly, the same distribution can be sampled without building it, with an extra cost of a logarithmic factor.
Vertex has ancestor chords. Sample with probability proportional to by the alias method, sample uniformly in , and take the -th ancestor of by binary lifting. Repeat until there are distinct extra edges.
Binary lifting
std::vector<std::vector<int>> binary_lifting(const std::vector<int>& parent) {
	int n = parent.size();
	int lg = 0;
	while ((1 << lg) <= n)
		lg++;
	std::vector<std::vector<int>> up(lg, std::vector<int>(n));
	for (int v = 0; v < n; v++)
		up[0][v] = parent[v];
	for (int j = 1; j < lg; j++)
		for (int v = 0; v < n; v++)
			up[j][v] = up[j - 1][up[j - 1][v]];
	return up;
}

int ancestor(const std::vector<std::vector<int>>& up, int u, int k) {
	for (int j = 0; j < (int)up.size(); j++)
		if (k >> j & 1)
			u = up[j][u];
	return u;
}std::vector<std::pair<int, int>> gen_skewed(int n, int m, int e, int spread) {
std::vector<int> parent(n), depth(n, 0);
std::vector<std::pair<int, int>> edges;
parent[0] = 0;
for (int i = 1; i < n; i++) {
parent[i] = wnext(i, e);
depth[i] = depth[parent[i]] + 1;
edges.emplace_back(parent[i], i);
}
auto up = binary_lifting(parent);
std::vector<int> w(n);
for (int u = 0; u < n; u++)
w[u] = std::max(0, std::min(spread, depth[u]) - 1);
alias_method a(w);
std::set<std::pair<int, int>> extra;
while ((int)extra.size() < m - (n - 1)) {
int u = next(a);
int k = next(2, std::min(spread, depth[u]));
extra.emplace(ancestor(up, u, k), u);
}
for (auto [v, u] : extra)
edges.emplace_back(v, u);
return edges;
}Algorithm 2: the same extra edges, without listing the candidates.
Theorem 1: Algorithm 2 has the same extra-edge distribution as Algorithm 1. Algorithm 1 runs in time if is . Algorithm 2 runs in expected time.
Proof: Let be the number of candidate chords, and write . Each candidate is a unique pair with , so . Algorithm 2 samples with probability and then uniformly in , hence each pair has probability
Sampling distinct values uniformly with rejection yields a uniformly random subset of the given size, matching choose in Algorithm 1. (Vertices with are never returned by the alias method.)
The lifting table is , and the alias table is . One uniform chord is generated in time (via binary lifting). Generating distinct values from a uniform sampler that takes time takes expected time, by the distinct-generation argument of miniblog 1. Here extra edges, so this is expected.
References
Random trees (miniblog 4): https://codeforces.com/blog/entry/156658
Alias method (miniblog 3): https://codeforces.com/blog/entry/156111
Distinct generation (miniblog 1): https://codeforces.com/blog/entry/154593
Level ancestor / binary lifting (Wikipedia): https://en.wikipedia.org/wiki/Level_ancestor_problem